Do chatbots inflate online review ratings? What a Journal of the Academy of Marketing Science study found
More firms now ask for reviews through a chat window instead of a form. Four studies show that the more humanlike the bot, the higher the stars, while the words that come with them get shorter and less useful.
Tsekouras et al. find reviews gathered by chatbot score up to 16% higher than those from a plain form, yet run about 42% shorter and help readers less.
Marketing in 3 · 2024 in research · No. 23 · Paper published 6 June 2024
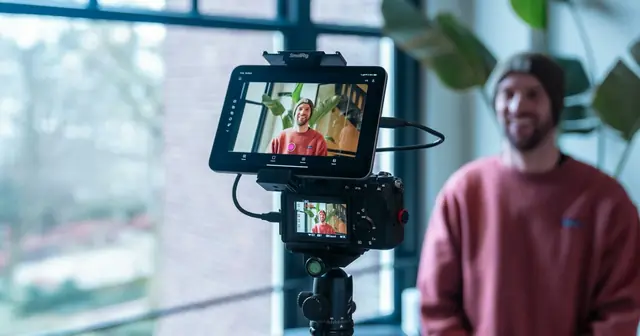
A wink, a name and a friendly word, and the stars start to climb. Photo: Enchanted Tools on Unsplash.
The short answer
Yes, they can. Across four studies, people gave the same product higher marks when a chatbot asked for their review than when a standard form did. A bot with a name, a face and a chatty, personal manner pushed scores highest. The written part suffered at the same time: reviews gathered in chat were shorter, and other readers found them less helpful when choosing.
Evidence level
★★★One study
★★★Several studies
★★★Meta-analysis
Key takeaways
In a live statistics course, students rated the same teaching videos 4.38 out of 5 when a chatbot asked and 3.79 when a form did, about 16% higher.
Pooling all four studies, a plain chatbot raised ratings by 0.35 standard deviations over a form, and a humanlike bot by 0.62.
In the final study, reviews written through the plain chatbot ran about 42% shorter than those written on a form.
Weak products gained most from the chat: a deliberately clumsy survey scored 8.05 out of 10 in chat against 7.37 on a form, while a well-made one barely moved (8.78 against 8.66).
What the researchers did
Dimitrios Tsekouras and Dominik Gutt of Erasmus University Rotterdam and Irina Heimbach of WHU Otto Beisheim School of
Management in Vallendar, Germany, looked at a small change in how firms ask for feedback. More and more shops now request a
review through a chat window, on their own site or inside a messaging app, rather than through the familiar page of stars
and boxes. Their question: does the way you ask change the answer you get?
They lined up three ways of asking. The first was an ordinary form. The second was a plain chatbot with a bot icon, a few
emojis, greetings and thank-yous. The third was Emma, a bot with a woman's photo, a first name, chat in the first person,
plenty of emojis, the customer's own name and an "is typing" signal. Every version asked the same questions in the same order.
Four studies followed: a field test in a real university course, two online experiments in which people watched a short
clay animation and then reviewed it, and a two-step test in which one group wrote reviews and another judged how helpful they were.
Study 1
68 undergraduates on a statistics module at a mid-sized university in Germany rated its teaching videos, by form or by chatbot, in November 2022
Study 2
1,112 US adults on Prolific reviewed a short film through the form, the plain bot or Emma, each with or without emotional language
Study 3
161 UK adults used one of the two bots, with the request coming either from the film's maker or from an independent review site
Study 4
203 Mechanical Turk workers reviewed a survey they had just taken; 303 more workers each rated five pieces of that feedback
Measured
Ratings (1 to 5 in the course, 1 to 10 online), review length, how enjoyable the exchange felt, how much it felt like dealing with a person, and helpfulness
Also reported
A fifth, supplementary study and a pooled analysis across the four main studies
How much the chat lifted the stars
The field test came first. On days with no classes, the lecturer posted a link asking students to rate the course videos,
and each click was routed at random to the form or to the chatbot. Nobody could tell beforehand which they would get, and
the questions were identical.
The big online experiment then added the middle step. People watched the same short film and then reviewed it in one of the
three set-ups. Both bots drew higher scores than the form, and Emma edged ahead of the plain bot, though by too little
to be sure in this study. Whether the bot used emojis, exclamation marks and warm adjectives did not change the scores.
In the UK study, Emma again beat the plain bot. A further study in the web appendix, with 350 people and a second video on
fixing a bike chain, put the plain bot ahead of the form once more.
Average rating of the same short film, by how the review was requested (1 to 10 scale)
Average rating of the same short film, by how the review was requested (1 to 10 scale)
Group
Value ()
Standard form
4.64
Plain chatbot
5.03
Humanlike chatbot (Emma)
5.16
Study 2, US adults on Prolific, about 370 per group, all rating the same clay animation.
Why a chat earns kinder scores
The authors trace the lift to two feelings, and which one matters depends on how human the bot seems. Going from a form to
the plain bot mainly made the exchange more enjoyable. That pleasure appears to rub off on whatever is being rated, much as
a cheerful checkout can colour how you remember a shop. Going from the plain bot to Emma added little extra enjoyment but a
stronger sense of human contact. When someone seems to be listening, people tend to soften bad news and say what they think
the listener wants to hear.
Two obvious fixes did not help. Stripping the emotional language out of the bot left the enjoyment route intact. And having
an independent review site ask, rather than the film's maker, did not weaken the human-contact route, even though people said
they tailored their words more to the maker. Neither tweak, on this evidence, is a reliable way to remove the bias.
How the exchange felt, by way of asking (1 to 7 scale)
How the exchange felt, by way of asking (1 to 7 scale)
Group
Value ()
Enjoyment, form
4.08
Enjoyment, plain bot
4.71
Enjoyment, humanlike bot
4.78
Human contact, form
3.18
Human contact, plain bot
3.63
Human contact, humanlike bot
3.99
Study 2, the same 1,112 adults, group averages from the web appendix (Table D-2). Enjoyment jumps as soon as there is a chat; human contact keeps climbing with Emma.
Shorter reviews, and less use to the next shopper
Star ratings are only half of a review. In the final study, Mechanical Turk workers first took a survey about their own work
on the platform and then reviewed it, either on a form or with the plain bot. A separate group read five of those reviews
each and scored how helpful, useful and informative they were, as if deciding whether to take the task themselves.
Chat reviews lost out, and word count accounts for the whole gap: once the authors allowed for length, the chat itself made
no further difference to how helpful a review seemed.
Why would a chat make people write less? The answer may lie in how conversation works. Talking to someone who feels present,
we assume they share our context and leave things out, saying "pass me that one" instead of "pass me the blue mug on the top
shelf". A chat window invites the same shorthand, and shorthand tells a stranger very little.
An ethics question as much as a design one
The authors present their findings as a warning to firms, shoppers and regulators. A seller who knows that a humanlike bot
nudges ratings up, and keeps using one, is showing buyers a product that looks better than customers found it. The
temptation is greatest for sellers whose products would otherwise score poorly.
Some brakes are built in. Thin reviews persuade the next buyer less well, and flattering scores hide what a product
needs fixing, so the firm loses out as well. Platforms that police review quality would need either to keep chatbots away from ratings or to set rules for them,
and the authors doubt such rules would be easy to write, given that their own fixes failed. They suggest that regulators
extend existing guidance on asking for reviews, such as the US Federal Trade Commission's, to cover chatbots.
Marketing in 3 steps
Ready. Set. Market.
1
ReadyDecide and prepare
List where you ask for ratings. Write down every place customers are asked to rate you: emails after purchase, app pop-ups, chat windows, codes printed on receipts. Next to each one, note whether a form or a conversation asks the question.
Choose a plain form for public stars. For any rating that will show on a product page or a review site, use a simple form. Leave out the agent's name, the face and any friendly replies between questions.
2
SetBuild it
Tone down any chat you keep. Where a chat has to ask for feedback, remove the human name, the staff photo and the typing signal. Do not let it agree with the customer or thank them by name before the rating is given.
Give the text box three prompts. Split the written part into three short boxes: what you liked, what you did not like, and your overall verdict. Ask for at least two sentences in each, so every review carries some detail.
3
MarketLaunch and measure
Trial chat against the form first. Before switching channels, send half your buyers to the chat and half to the form for two weeks. Compare the average star rating and the average number of words from each half.
Label and track every review's source. Store the collection channel with every review. Each month, check whether chat reviews score higher and run shorter than form reviews, and tell readers on the page how reviews were gathered.
Found this useful?
Marketing in 3 is free and ad-free, with new issues every Monday and Thursday. A coffee keeps it that way.
A modest lift, not a makeover. In the online studies, chat added roughly 0.3 to 0.5 of a point on a ten-point scale, or roughly 0.15 to 0.25 of a star once shown on a five-star display. The classroom gap was wider, so treat these as typical rather than as a ceiling.
More engagement at the end. In the survey study, people reviewing in chat were more likely to leave extra feedback when invited, and dropout during the review was 4.7% lower than on the form.
Internal surveys may read kinder too. The field test was a course evaluation, not a shop review. That hints, though nobody tested it, that satisfaction surveys run through a chat could flatter in the same way.
The fun may fade. The authors expect the novelty of chatting with a bot to wear off as chatbots become routine, which could weaken the enjoyment route. Whether the feeling of a person on the line fades too is untested.
Where it does not work
Films and surveys, not shopping baskets. The rated items were teaching videos, a 90-second clay animation and an online questionnaire. Physical goods, services and costly purchases were not tested.
Paid panels and one classroom. Most people took part through paid online panels in America and Britain, and the field test drew on a single course at one German university.
Not every result was clear-cut. Emma's edge over the plain bot in the UK study, and the extra lift for the clumsy survey, cleared only a loose 10% threshold. Reviews were significantly shorter in only two of the four studies.
The plain bot did not feel more human. In the largest study, people rated it no more humanlike than the form (4.19 against 4.10 out of 7), yet it still lifted scores, mainly through enjoyment.
No working remedy yet. Minimum word counts or structured review templates are ideas the authors leave for future research; none was tested here.
Questions marketers ask
Are star ratings higher when a chatbot collects them?
They can be. In four separate studies, products scored higher when a chat gathered the feedback than when people filled in an ordinary form, and the most humanlike bot drew the highest marks (Tsekouras et al., 2024).
Why would chatting with a bot make someone rate a product more generously?
Two forces seem to be at work. A conversation is more fun than a form, and the good mood transfers to the product. A named bot with a photo also makes it feel as if someone is listening, and most of us go easy on criticism when we sense an audience.
Does telling customers they are talking to a bot remove the bias?
There is no sign that it does. In a pretest with about 560 people, scores barely moved when the chatbot openly introduced itself as software. In the main studies, nobody was told whether a human or a machine was asking.
Are reviews collected by chatbots less useful to shoppers?
They tend to be. Readers judged chat reviews less helpful, and also a little less credible and persuasive. Each of those gaps traced back to length: shorter texts simply carried less of the detail people look for before buying.
Shoppers in four countries with very different cultures, 1,259 in all, were surveyed about the personal data they hand to retail loyalty schemes in return for perks. People who disliked uncertainty, and those living by more collective norms, voiced sharper privacy worries, and cultural values also shaped how far members trusted the retailer and stayed loyal. The authors looked at culture both in each person's own values and at the level of whole countries. One data promise will rarely fit every market a scheme runs in.
Five studies asked when people let an AI tool choose a present. How close the giver felt to the recipient made a clear difference: a gift for someone close is meant to say something about the relationship, and expecting that signal held people back from the tool. A tool that could chat back and forth drew more use, especially for gifts to close friends. For personal occasions, a gift finder that can hold a conversation may stand a better chance.
Source
Tsekouras, D., Gutt, D., & Heimbach, I. (2024). The robo bias in conversational reviews: How the solicitation medium anthropomorphism affects product rating valence and review helpfulness. Journal of the Academy of Marketing Science, 52(6), 1651-1672. https://doi.org/10.1007/s11747-024-01027-8
This brief is written for practitioners from the published article. Open access (CC BY 4.0): free to read at the publisher. Numbers are as reported by the authors; read the article for full methods.
Haenlein et al. define synthetic word of mouth, where AI writes, carries, judges or acts on recommendations, and how people judge what looks machine-made.
Fang et al. tested keep-it partial refunds on 853,521 online shoppers: the first return cost more, but later spending left a net gain of $1.44 per customer.
Schivinski's machine learning study of 1,356 brand followers found five engagement patterns driven by commitment, and they still matter in the age of AI.
Bruno Schivinski is Associate Professor of Marketing at Gdańsk University of Technology. He studies how consumers engage with brands in digital and social media.